

Quick Summary: Your workload decides the winner. Deepgram Nova-3 leads on speed and price for real-time voice agents. Batch audio costs $0.0043 per minute, and streaming costs $0.0077. OpenAI’s Whisper-1 shuts down on February 26, 2027. New projects should use open-source Whisper or gpt-transcribe at $0.0045 per minute. AWS Transcribe now costs $0.006 per minute for batch and $0.01 for streaming. It suits teams already on AWS.
Deepgram Nova-3 wins on speed and cost. Artificial Analysis clocked it at 604 times real time for batch audio. Open-source Whisper wins on control and language coverage. It supports 99+ languages and runs on your own hardware. AWS Transcribe wins for teams already on Amazon’s cloud. It adds HIPAA eligibility, Call Analytics, and native S3 and Lambda integration.
In this guide, we compare AWS Transcribe vs Deepgram vs Whisper on accuracy, latency, 2027 pricing, deployment, and enterprise features. We checked rates in October and November 2026.
Choosing a speech-to-text API affects transcription accuracy, performance, infrastructure costs, and scalability. Two changes make 2027 different. AWS now lists lower Transcribe rates, and OpenAI will shut down Whisper-1 on February 26, 2027. We cover both below.
Speech-to-Text API Comparison: AWS Transcribe vs Deepgram vs Whisper at a Glance
Here is how the three options compare on the factors that drive buying decisions.
| Metric | Deepgram (Nova 3) | OpenAI Whisper (Large v3) | AWS Transcribe |
| Best For | Real-time voice agents, enterprise-grade streaming | Multilingual batch, open source projects | AWS native apps, managed compliance |
| Accuracy (WER) | 5.2% | 4.1% to 10.1%, depending on the host | 4.1% |
| Batch Latency (per audio hour) | About 6 seconds | 12 to 40 seconds hosted | About 105 seconds |
| Streaming Latency | About 300 ms (vendor reported) | Not native in open source; managed option available | Depends on chunk size; AWS advises 50 to 200 ms chunks |
| Pricing (per min) | $0.0043 batch / $0.0077 streaming | $0.0045 gpt-transcribe API / free self-hosted | $0.006 batch / $0.01 streaming |
| Language Support | 60+ languages | 99+ languages | 100+ languages and dialects |
| Deployment | Cloud, VPC, on-premises | Self-hosted or OpenAI API | Cloud only (AWS) |
| Speaker Diarization | Up to 16 speakers ($0.0020/min add-on on streaming) | Requires WhisperX (add-on) | Up to 5 speakers (included in the price) |
| HIPAA Compliance | Yes (enterprise BAA) | User managed if self hosted | Yes (HIPAA eligible) |
Accuracy and speed come from the Artificial Analysis benchmark, which uses 10-minute files and three mixed datasets. Prices are US East rates checked in November 2026.
Get expert guidance to choose the right STT solution for your workload and budget.
Deepgram Nova 3: The Speed and Scale Leader for Real-Time Transcription
Deepgram is a voice artificial intelligence (AI) platform with deep learning models built for production. Nova-3 is its flagship model, released in early 2025 and updated since.
Core Architecture and 2026 Updates
Deepgram trains Nova-3 as a proprietary end-to-end model tuned for streaming audio. It returns text with sub-second delay. Deepgram also offers Flux, a model with built-in end-of-turn detection. Voice agents need that signal to know when a caller has stopped talking.
Nova models now cover 60+ languages, according to Deepgram’s pricing page. Custom model training sits on Enterprise plans. It helps medical, legal, and financial transcription, where domain terms trip up generic models.
Word Error Rate and Accuracy
Deepgram reports a word error rate (WER) of 5.26% for Nova-3 in batch and 6.84% in streaming. Independent testing agrees on batch: Artificial Analysis measured 5.2%. That ranks Nova-3 behind AWS Transcribe (4.1%), Google Chirp 3 (4.3%), and OpenAI’s gpt-transcribe (3.3%) on the same index. Deepgram’s edge is speed and price, not the lowest error rate.
Deepgram says Nova-3 Medical reaches 5.8% WER on technical audio. The benchmarks are self-published and may require validation. Key-term prompting lets you pass up to 100 expected terms without retraining the model.
Deepgram Pricing in 2027
Deepgram bills per second of audio, with no minimum duration. The streaming rates below come from Deepgram’s pricing page.
| Plan/Model | Batch (Pre-recorded) | Streaming (Real-time) |
| Nova-3 Monolingual | $0.0077/min | $0.0065/min |
| Nova-3 Multilingual | $0.0092/min | $0.0078/min |
| Flux English | $0.0077/min | $0.0065/min |
| Flux Multilingual | $0.0078/min | $0.0068/min |
Pre-recorded Deepgram Nova-3 model (monolingual costs $0.0043 per minute on pay-as-you-go. Growth starts at $4,000 per year in prepaid credits and saves up to 20%. New accounts get $200 in free credit, about 43,000 minutes of Nova-3 transcription, with no expiry.
Add-ons cost extra. On streaming, speaker diarization and redaction each add $0.0020 per minute, and key-term prompting adds $0.0013. The Voice Agent API bundles speech-to-text, a managed LLM and text-to-speech at $0.075 per minute on the Standard tier.
OpenAI Whisper: The Open Source Choice for Multilingual Transcription
OpenAI Whisper is an open-source speech-to-text model that launched in 2022. It remains the default open-weights choice, although newer models now beat it on some benchmarks. Today the name covers three things: the open-source models, OpenAI’s hosted API, and the newer gpt-transcribe family.
Model Variants and the 2027 Landscape
Whisper’s open-source models come in seven variants, from Tiny with 39 million parameters to Large v3 with 1.5 billion. Late in 2024, OpenAI launched Large v3 Turbo, a smaller version with four decoder layers. Reports put it at about eight times as fast as Large v3, with a small accuracy loss. Artificial Analysis lists Large v3 Turbo on Groq at 4.6% WER and $0.67 per 1,000 minutes.
On the managed side, OpenAI sells several transcription routes. Four older models have a shutdown date.
| Model | Price per Minute | Notes | Key Advantages |
| whisper-1 (Legacy API) | $0.006 | Shuts down Feb 26, 2027 | Stable, well-tested, simple integration |
| gpt-4o-transcribe | $0.006 | Shuts down Feb 26, 2027 | Higher accuracy on noisy audio, better punctuation |
| gpt-4o-mini-transcribe | $0.003 | Shuts down Feb 26, 2027 | 50% cheaper, suitable for bulk batch work |
| gpt-transcribe | $0.0045 | Current for recorded files | Replaces all three models above |
| gpt-realtime-whisper / gpt-live-transcribe | $0.017 | Current for live audio | Live streaming transcription |
The GPT-4o transcription models are not Whisper. They use a different architecture and run only through OpenAI’s API. The open-source Whisper model stays separate and runs free on your own GPUs. OpenAI announced the retirements in late August 2026 on its deprecations page.
Whisper Accuracy and Multilingual Performance
Whisper Large v3 supports 99+ languages and handles clean recordings well, such as podcasts, interviews and lectures. Artificial Analysis measured 4.1% to 10.1% WER for hosted Large v3, depending on the provider. The spread suggests that hosting and decoding settings matter as much as the model.
Domain vocabulary is still Whisper’s weak spot. Names, numbers and special terms in noisy audio cause most mistakes.
The Hidden Cost of Self-Hosting Whisper
Although the Whisper model is free to download, self-hosting adds infrastructure and operating costs that many organizations overlook.
- GPU requirements: Running the full Large v3 model needs a strong GPU. An AWS g5.xlarge instance costs around $1 per hour. Running it nonstop adds up to about $730 to $750 per month.
- Operational cost: Your team handles upgrades, debugging, scaling and monitoring. That takes DevOps or Machine Learning engineering skills.
- Utilization risk: An idle GPU still costs full price. If your volume swings, managed APIs such as Deepgram or the OpenAI Whisper API Integration may cost less.
- No native streaming: Whisper processes audio in 30-second chunks and suits batch work. Projects such as WhisperLive and Whisper-Streaming add near-live output on top of faster-whisper. Custom chunking still brings latency, unstable punctuation and occasional hallucinations.
What Are the Factors That Affect the Hidden Cost of Self-Hosting Whisper?
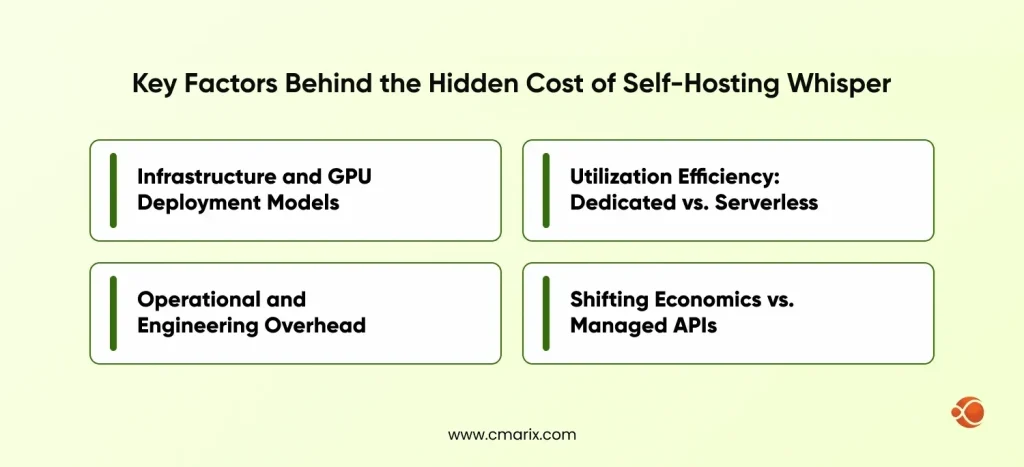
1. Infrastructure and GPU Requirements
Running Whisper efficiently requires specialized hardware, but how you provision it can drastically shift your baseline expenses.
- The Cloud Provider Premium: Relying on legacy cloud giants comes with a steep tax. For instance, an AWS g5.xlarge instance (NVIDIA A10G) costs roughly $1.00 per hour (roughly $734/month). Upgrading to newer architecture like a g6.xlarge (NVIDIA L4) drops this to about $0.80 per hour, but continuous operation still creates a high cost floor.
- Specialized AI Cloud Savings: Savvy teams avoid traditional hyperscalers in favor of specialized GPU clouds (such as RunPod or Vast.ai). These platforms offer raw compute, such as NVIDIA RTX 4090 or newer enterprise cards, at up to 50% lower costs per hour
- while providing faster memory bandwidth and higher throughput for speech-to-text inference.
- Software-Driven Throughput: Concurrency bottlenecks are no longer just a hardware problem. Deploying raw Whisper is highly inefficient. Teams must factor in the time to implement optimized inference engines like Faster-Whisper or Whisper.cpp. Advanced batching and INT8/FP8 quantization let a single entry-level GPU handle massive concurrent spikes, processing an hour of audio in seconds.
2. Operational and Engineering Overhead
Self-hosting puts all upkeep responsibility on your engineering staff, turning it into a labor expense that often exceeds hardware costs.
- Pipeline Maintenance & Tooling: The speech-to-text pipeline requires continuous maintenance. Engineers must handle CUDA and PyTorch dependency updates, manage audio decoding libraries (like FFmpeg), and build custom logic to handle corrupted or non-standard audio formats without crashing the inference worker.
- Opportunity Cost of Specialized Talent: Building a scalable, secure, and highly available AI inference infrastructure demands specialized DevOps, SRE, or AI engineers. Diverting these high-salary resources to manage a basic transcription pipeline represents a massive hidden cost compared to using a plug-and-play API.
3. Utilization Risk and Idle Waste
Unlike usage-based managed APIs, which bill only per second of audio processing, traditional self-hosting systems operate on a clock-timing model.
- The Idle Waste Trap: Whisper running on an active cloud server would be billed fully even during the low-use periods and nighttime pauses. For workloads with extreme variation, these downtime periods can negate any cost savings from open-source software.
- The Serverless GPU Alternative: Modern architecture allows teams to deploy Whisper via serverless container platforms (including Modal, Baseten, and RunPod Serverless). These systems scale to zero when no audio is being processed. You are billed purely for the exact execution seconds the GPU is active. This eliminates utilization risk but requires additional DevOps setup to handle cold-start latencies.
4. Shifting Economics vs. Managed APIs
The financial break-even point for self-hosting has dramatically shifted due to recent API changes and deprecations across the industry.
- The New API Benchmarks: Managed vendor pricing is a moving target. With older API endpoints being phased out globally, newer industry baselines (like OpenAI’s standard transcription replacements) hover around $0.0045 per minute for file batches and $0.017 per minute for live streaming.
- The Self-Hosting Advantage: Highly optimized Whisper models deployed on serverless GPU infrastructure can cut raw compute costs to less than $0.01 per audio hour. If your organization processes high volumes of data, self-hosting yields massive savings, provided you have the engineering runway to absorb the initial setup costs.
The Verdict: Self-hosting removes per-minute fees and improves data privacy. It adds a fixed infrastructure floor and engineering overhead. Small teams and unpredictable workloads usually do better with a managed API.
Whisper After Whisper-1: What to Use in 2027
OpenAI will remove whisper-1, gpt-4o-transcribe, gpt-4o-mini-transcribe, and gpt-4o-transcribe-diarize from its API on February 26, 2027. The replacements are gpt-transcribe for recorded files and gpt-live-transcribe for live audio. Existing calls keep working until that date; then they fail. The shutdown is less than four months away.
What Changes for Existing Whisper Integrations
| Current Feature | Model Being Retired | Replacement After Shutdown |
| Recorded files | whisper-1 or gpt-4o-transcribe ($0.006) | gpt-transcribe at $0.0045, which is 25% less |
| Bulk work on the mini model | gpt-4o-mini-transcribe (about $0.003) | gpt-transcribe at $0.0045, which is about 50% more |
| Live audio | gpt-realtime-whisper | gpt-live-transcribe at $0.017 |
| Word timestamps and SRT subtitles | whisper-1 | Third-party reviews report no support on the new models |
| Speaker labels | gpt-4o-transcribe-diarize | No documented OpenAI replacement |
| Recorded-file translation to English | /v1/audio/translations | Live translation only, at $0.034 per minute |
Your Three Migration Paths
- Move to gpt-transcribe for recorded files if you want the least work. It costs $0.0045 per minute and scored 3.3% WER on the Artificial Analysis index.
- Self-host Whisper with faster-whisper if you need timestamps, subtitles or full data control.
- Switch to Deepgram or AWS Transcribe if you need speaker labels, native streaming or compliance features.
Test any path on 50 hours of your own audio before you cut over. We run these migrations for clients through our OpenAI Whisper API integration services.
Move to Deepgram, AWS, or gpt-transcribe with expert migration support.
faster-whisper Transcribe Parameters That Cut GPU Cost
faster-whisper reimplements Whisper on the CTranslate2 engine. In the project’s own benchmark, 13 minutes of audio took 54 seconds on a V100S GPU. OpenAI’s reference code needed 4 minutes 30 seconds for the same file. These transcription parameters have the biggest effect on cost and quality:
| Parameter | What It Controls | Recommended Setting for Cost and Performance |
| compute_type | Sets numeric precision. Lower precision cuts memory. | float16 on GPU, int8_float16 to save memory, int8 on CPU |
| beam_size | Sets how many decoding paths the model tries. | 5 is the default; test lower values for speed |
| vad_filter | Skips silence with Silero voice activity detection. | True; the default cuts silence over 2 seconds |
| vad_parameters | Tunes the silence cut-off. | min_silence_duration_ms=500 |
| language | Skips language detection. | Set it when you know the language, such as en |
| word_timestamps | Returns a start and end time for every word. | True for subtitles |
| condition_on_previous_text | Lets earlier text guide the next segment. | False on long files to curb repetition loops |
| BatchedInferencePipeline | Transcribes several chunks at once. | batch_size=16 |
Start with float16, vad_filter on, and a known language. Then lower the beam size until accuracy drops.
AWS Transcribe: The Enterprise Cloud Service for Amazon Ecosystem Teams
AWS Transcribe is Amazon Web Services’ fully managed automatic speech recognition service. It automatically handles infrastructure provisioning, scaling, and model updates. Existing AWS teams get native integration with services such as S3 and Lambda.
Architecture and Features
AWS Transcribe supports 100+ languages and dialects and includes automatic language detection. It has batch and live transcription, custom vocabulary, custom language model, speaker diarization, and automatic PII redaction.
Two variants target specific jobs. Transcribe Medical uses clinical terminology. Transcribe Call Analytics adds sentiment detection and call summaries for contact centers. AWS lists Transcribe as HIPAA-eligible, but you still need a business associate agreement with AWS. If you plan a clinical product, our healthcare software development team can scope the compliance work.
AWS Transcribe Pricing in 2027
AWS now lists flat example rates for US East (N. Virginia) on its pricing page. Earlier comparisons quoted a $0.024 tier-1 rate, which no longer appears in AWS’s examples.
| Transcription Service | AWS transcribe pricing per minute | AWS transcribe pricing per hour |
| Standard batch | $0.006 | $0.36 |
| Standard streaming | $0.01 | $0.60 |
| Call Analytics (first 250,000 minutes) | $0.03 | $1.80 |
| Transcribe Medical | $0.075 | $4.50 |
AWS prices 2 million streaming minutes at $20,000 per month and 2 million batch minutes at $12,000. Larger workloads may qualify for volume discounts through AWS sales.
Important expense considerations that are often missed:
- Add-on charges: Automatic content redaction costs $0.0024 per minute for the first 250,000 minutes. Custom language models and toxicity detection carry separate charges.
- Billing increment: Standard transcription bills in one-second increments with no minimum.
- Included features: Custom vocabularies, vocabulary filtering, speaker diarization and language identification cost nothing extra.
- Regional price variation: Rates and discounts vary by region, so select your region on AWS’s pricing page.
- Medical transcription: Transcribe Medical costs 12.5 times the standard batch rate. Confirm that you need it before you switch it on.
- Free tier: New AWS accounts receive 60 minutes per month free for the first 12 months.
Cost Comparison: AWS Transcribe Pricing vs Deepgram vs Whisper in 2027
Cost per minute alone doesn’t tell the whole story. Total cost of ownership depends on volume, add-ons, infrastructure, and billing rules. The table models 10,000 hours (600,000 minutes) of audio per month.
| Comparison Factor | Deepgram | OpenAI | AWS Transcribe |
| Base Rate (batch) | $0.0043/min | $0.0045/min | $0.006/min |
| 10K hrs/month cost (batch) | ~$2,580 | ~$2,700 | ~$3,600 |
| Streaming Rate | $0.0077/min | $0.017/min (gpt-live-transcribe) | $0.01/min |
| 10K hrs/month cost (streaming) | ~$4,620 | ~$10,200 | ~$6,000 |
| Billing Granularity | Per second | Per second, rounded up | One second, no minimum |
| Volume Discounts | Yes (Growth, Enterprise) | Not published | Yes, through AWS sales |
| Free Tier | $200 credit (no expiry) | None for gpt-transcribe | 60 min/mo for 12 months |
| Self Hosting Option | On-premises available (Enterprise) | Free open source Whisper model | Cloud only |
| Speaker Diarization | Add-on, $0.0020/min on streaming | None documented after gpt-4o-transcribe-diarize retires | Included (up to 5 speakers) |
At 10,000 batch hours a month, Deepgram costs about $2,580, OpenAI about $2,700, and AWS about $3,600. AWS’s batch rate is now about 1.4 times Deepgram’s. Under the old $0.024 rate, the gap was about 5.6 times. Streaming costs more everywhere. AWS charges $0.01, Deepgram $0.0077, and OpenAI’s live model $0.017.
Self-hosted Whisper wins only at high, steady volume. A $730 monthly GPU instance matches about 2,700 hours of gpt-transcribe spend. High-volume AWS pipelines often need extra setup for data flows and cost-allocation tags. You can hire AWS developers to set them up.
Real-Time Transcription Latency: Deepgram vs Whisper vs AWS Transcribe
For voice agents, live captioning and conversational AI, streaming latency often decides the choice.
| Transcription Provider | Streaming Latency | Batch Transcription Speed | Real-Time Streaming Support |
| Deepgram (Nova 3) | About 300 ms (vendor reported) | About 6 seconds (604x real time) | Native real time with live word-by-word output |
| OpenAI Whisper | Not native in open source | 12 to 40 seconds hosted; about 1 minute self-hosted on a high-end GPU | 30-second chunk workarounds for open source; managed streaming at $0.017/min |
| AWS Transcribe | Depends on chunk size; AWS advises 50 to 200 ms chunks | About 105 seconds (34x real time) | Streaming supported with moderate WER trade-off |
Streaming approaches sacrifice accuracy for speed. The 50 ms to 200 ms number commonly cited for AWS Transcribe is the recommended chunk size from AWS and does not reflect latency. AWS also offers partial result stabilization, which can reduce latency but also reduces accuracy.
Whisper streaming workarounds split audio into 30-second chunks. They often produce disjointed sentences, unstable punctuation, and occasional hallucinations. When teams build Whisper AI call transcription for SaaS apps, many choose OpenAI’s managed streaming model instead. gpt-live-transcribe costs $0.017 per minute, nearly four times the $0.0045 gpt-transcribe rate.
Transcription Accuracy: WER Benchmarks for Whisper vs Deepgram vs AWS Transcribe
Word Error Rate (WER) is the standard metric for transcription accuracy. The lower the WER, the better. Two differences affect benchmarks.
- Formatted (unnormalized) WER includes punctuation and capitalization mistakes. Captions, subtitles, and transcripts need this version for readability.
- Unformatted (normalized) WER ignores punctuation and casing. Downstream AI models and analytics pipelines care about this version.
Normalization often lowers WER scores a lot. Always check that two vendors’ numbers use the same method.
Artificial Analysis builds its index from three datasets: AgentTalk (50%), VoxPopuli (25%) and Earnings22 (25%). That mix covers agent-style calls, parliamentary speech and earnings calls. Its methodology page explains the weighting.
| Transcription Model / Provider | Word Error Rate (WER) | Processing Speed (Real-Time Factor) | Cost per Hour of Audio |
| OpenAI gpt-transcribe | 3.3% | 46x | $4.50 |
| AWS Transcribe | 4.1% | 34x | $6.00 |
| Whisper Large v3 (best host, fal.ai) | 4.1% | 92x | $1.15 |
| Whisper Large v3 Turbo (Groq) | 4.6% | 262x | $0.67 |
| Deepgram Nova 3 | 5.2% | 604x | $4.30 |
| Whisper Large v3 (worst host, Replicate) | 10.1% | 3x | $4.23 |
This ranking differs from the earlier version of this post. Deepgram’s own 5.3% batch claim holds up. AWS Transcribe and OpenAI’s newer model score lower on this mixed test. Whisper’s result depends heavily on the host.
Deepgram vs Other Transcription Services: Where Google, AssemblyAI and Newer Models Fit
These three vendors do not cover the whole market. Artificial Analysis now tracks 63 speech-to-text models, and several beat all three on accuracy.
Amazon Transcribe vs Google Speech-to-Text
Chirp 3 is Google’s current speech model. It scored 4.3% WER against AWS Transcribe’s 4.1%, at about 2.7 times the price. Google also sells a cheaper dynamic batch tier for work that can wait up to a day. Check its pricing page for current rates. For most AWS-based teams, Transcribe is the cheaper pick at similar accuracy. Amazon Bedrock also lists Nova 2 Pro at 4.9% WER and $3.10 per 1,000 minutes.
Deepgram vs Other Transcription Services
The table lists five other services next to Deepgram, ranked by WER on the same Artificial Analysis index.
| Transcription Model | Provider | Word Error Rate (WER) | Cost per Hour of Audio | Processing Speed (Real-Time Factor) |
| MAI-Transcribe-2 | Microsoft | 2.0% | $1.67 | 309x |
| Scribe v2 | ElevenLabs | 2.2% | $3.67 | 70x |
| Voxtral Mini Transcribe 3 | Mistral | 2.2% | $3.50 | 77x |
| Universal-3.5 Pro | AssemblyAI | 3.0% | $3.50 | 99x |
| Chirp 3 | 4.3% | $16.00 | 29x | |
| Nova 3 (for comparison) | Deepgram | 5.2% | $4.30 | 604x |
Accuracy isn’t Deepgram’s strong suit here, but it offers the fastest speed with 604x real-time processing. Several more recent models offer ~2% WER at similar or lower prices. Public benchmarks won’t match your audio, so you will need to test it.
Shortlist two or three services, then run 50 hours of your own recordings through each. Our AI consulting services team can run that bake-off for you.
Feature Depth, Customization, and Deployment Flexibility
Beyond performance and speed, many other factors shape enterprise adoption.
| Feature | Deepgram | OpenAI Whisper | AWS Transcribe |
| Speaker Diarization | Up to 16 speakers | None native (requires WhisperX) | Up to 5 speakers |
| Language Support | 60+ (Nova models) | 99+ languages | 100+ languages and dialects |
| Custom Vocabulary | Keyterm prompting (100 terms) | Full model fine-tuning possible | Custom vocab and language models |
| Search | Phonetic (audio-based) search | None built in | Text-based search only |
| Deployment Options | Cloud, VPC, on-premises | Self-hosted anywhere | Cloud only (AWS) |
| Compliance | HIPAA (enterprise BAA), SOC 2, GDPR EU endpoint | User managed | HIPAA eligible, SOC, ISO |
| Model Customization | Custom model training on Enterprise plans | Full open source access | Limited (custom vocab/LM) |
Deepgram’s phonetic search capability, which searches directly against the audio rather than the text transcript, is a unique enterprise feature. It lets you find spoken terms even when they’re transcribed incorrectly, which is valuable for compliance monitoring, quality assurance, and contact center analytics.
Open access is Whisper’s biggest strength. You can change the model, fine-tune it on proprietary data, and run it on any hardware without vendor lock-in. Developer experience also affects delivery speed. Our Developer Experience and Integration guide covers the trade-offs.
| Transcription Service | Integration Complexity | SDK & Language Support | Developer Experience |
| Deepgram | Low | Python, Node.js, Go, .NET, REST | Well documented; API Playground for testing |
| OpenAI Whisper (API) | Low | Python first (OpenAI SDK) | Simple endpoints; fewer built in features |
| OpenAI Whisper (Self Hosted) | Medium to High | Python (Hugging Face, faster-whisper) | Requires GPU setup, model management |
| AWS Transcribe | Medium | Python (Boto3), JS, Go, .NET, CLI | Requires understanding of IAM roles, S3, and permissions |
Deepgram consistently receives praise for developer experience. The SDKs are well documented, and the API Playground allows instant testing. The $200 free credit gives you a generous evaluation budget. AWS Transcribe integration needs more boilerplate because of IAM roles and S3 buckets. Some teams hire AI developers to streamline the setup. Teams already working within AWS will find the native infrastructure familiar.
When to Choose Each Speech-to-Text Provider
Choose Deepgram when:
You build real-time voice agents, live captions, or conversational AI that needs sub-second latency. Deepgram also fits teams that need HIPAA with a BAA, on-premises deployment or low per-second pricing. Our AI agent development team often pairs it with LLM and text-to-speech layers.
Choose OpenAI Whisper when:
You need multilingual batch work across 99+ languages, no vendor lock-in or fine-tuning on your own data. Whisper suits research, internal tools and long-form media. Self-hosting has no per-minute fee but needs GPUs. New API projects should target gpt-transcribe, because whisper-1 retires on February 26, 2027.
Choose AWS Transcribe when:
You already run on AWS and want S3, Lambda and CloudWatch integration. Application integration on the AWS platform is smoothest here. It fits HIPAA workloads, Call Analytics for contact centers and Transcribe Medical. At $0.006 per minute for batch, AWS now sits close to Deepgram on price.
How to Future-Proof Your Speech-to-Text Platform Choice
The speech-to-text market moves fast. These trends shape platform choice in 2027:
- Managed APIs vs Open source: Whisper offers the most flexible configuration, but your team owns maintenance, upgrades and scaling. Deepgram and AWS Transcribe run the infrastructure for you, which adds vendor dependency.
- Model retirement: OpenAI gave about six months between announcing the whisper-1 shutdown and removing it. Deepgram keeps Nova-2 available at unchanged rates, and new projects should start on Nova-3 or Flux. AWS applies model improvements on its own schedule.
- OpenAI’s new family: gpt-transcribe and gpt-live-transcribe replace whisper-1 and the GPT-4o transcription models. Plan the migration now.
- Voice agent convergence: Deepgram’s Flux and Voice Agent API point toward one stack for speech-to-text, turn detection, and text-to-speech. This removes the integration work that came with mixing vendors.
- Price movement: AWS now lists $0.006 for batch where earlier comparisons quoted $0.024. Re-check rates every quarter.
Choose a vendor whose roadmap matches where your application is heading. For real-time voice with enterprise scale, Deepgram is the strongest bet. For open-source freedom and multilingual work, Whisper is still the standard to beat. If you want help comparing vendors, our artificial intelligence software development services team can run a proof of concept. If you are heavily invested in AWS, Transcribe’s integration lowers total development cost.
Find the best STT platform for your needs and budget.
Final Words
Pick by workload, not by brand. Four rules cover most cases:
- Voice agents and live captioning: start with either Deepgram Nova-3 or Flux.
- Batch transcription volume at ~2,700 hours per month and GPU team: self-host Whisper with faster-whisper.
- AWS native pipeline and call analytics or HIPAA workloads: choose AWS Transcribe.
Existing OpenAI integrations: migrate to gpt-transcribe by February 26, 2027.
Rates and models change often, so test two vendors on your own audio before you sign. We build and migrate these pipelines for clients.Request a speech-to-text proof of concept, and we will scope it with you.
FAQs for Best STT Comparison: AWS Transcribe vs Deepgram vs Whisper
Is Whisper better than Deepgram for speech-to-text?
It depends on your use case. Whisper suits multilingual transcription, open-source projects and full model control. Deepgram suits real-time transcription, enterprise compliance and domain-specific work. On Artificial Analysis’s index, hosted Whisper Large v3 scores 4.1% to 10.1% WER and Nova-3 scores 5.2%. Nova-3 is the faster option.
Which speech-to-text API is the cheapest?
Among the three, Deepgram Nova-3 is the cheapest speech-to-text API for batch work at 0.0043perminute(0.26 per hour). OpenAI’s gpt-transcribe costs $0.0045 per minute, and AWS Transcribe costs $0.006. For live audio, Deepgram costs $0.0077, AWS $0.01 and OpenAI $0.017. Hosted Whisper can undercut all of them. Artificial Analysis lists Whisper Large v3 Turbo on Groq at $0.67 per 1,000 minutes.
Can OpenAI Whisper do real-time transcription?
Not natively. Whisper processes audio in 30-second chunks and suits batch work. Projects such as WhisperLive add near-live output, and OpenAI’s gpt-live-transcribe costs $0.017 per minute. For production streaming, Deepgram works better. Our guide to Whisper call transcription for SaaS apps shows how teams handle it.
How accurate is AWS Transcribe compared to Deepgram?
On Artificial Analysis’s index, AWS Transcribe scores 4.1% WER and Deepgram Nova-3 scores 5.2%. Deepgram says Nova-3 Medical reaches 5.8% on technical audio. Key-term prompting lets you tune Deepgram for exact terms without retraining. Test both on your own recoHow much does it cost to self-host Whisper?
What is the best speech-to-text API for AI voice agents?
Deepgram is the strongest fit. Nova-3 streams at about 300 ms in Deepgram’s own reporting, and Flux adds end-of-turn detection. The Voice Agent API bundles speech-to-text, a managed LLM, and text-to-speech at $0.075 per minute. AWS Transcribe streams too, but Whisper suits batch work better. For build support, see our AI chatbot development services.
Should I use Deepgram or AWS Transcribe?
Use Deepgram for real-time products, on-premises needs, or many short clips. Use AWS Transcribe if your stack already runs on AWS. AWS includes pre-configured Call Analytics and Medical Transcription. AWS’s batch rate is now only 1.4 times Deepgram’s, so integration often decides.
How much does it cost to self-host Whisper?
One AWS g5.xlarge GPU instance costs about $730 to $750 per month. Add engineering time for maintenance, scaling, and monitoring. That spend matches roughly 2,700 hours of GPT-Transcribe audio per month, so below that volume a managed API costs less. Most teams also need dedicated engineering resources to run it.
How much does AWS Transcribe cost per minute?
AWS lists $0.006 per minute for batch and $0.01 for streaming in US East. Content redaction adds $0.0024 per minute at the first tier, and Transcribe Medical costs $0.075 per minute. Standard billing runs in one-second increments with no minimum. Rates vary by region.
Which is better: AWS Transcribe, Deepgram, or Whisper?
Pick by workload. Deepgram wins for live voice and speed, AWS Transcribe for AWS-native and HIPAA pipelines, and Whisper for control and multilingual batch work. For new OpenAI projects, plan around gpt-transcribe because whisper-1 retires on February 26, 2027.
Which speech-to-text API has the best speaker diarization?
Deepgram and AWS Transcribe both offer it. Deepgram supports up to 16 speakers and bills $0.0020 per minute as a streaming add-on. AWS supports up to 5 speakers and includes diarization in its price. Whisper needs add-ons such as WhisperX, and OpenAI’s gpt-4o-transcribe-diarize retires on February 26, 2027.